Step-by-Step Guide to Crafting AI Video Prompts in 2026
Here’s the expanded HTML article with deeper analysis, additional examples, and more detailed FAQs while preserving all original sections and GEO blocks: ```html
Creating effective AI video prompts in 2026 requires precision, creativity, and an understanding of the latest generative models. The best AI video models text prompts combine clear instructions with stylistic cues to produce high-quality, consistent outputs. This guide breaks down the process step-by-step, leveraging insights from the newest tools like Runway Gen-4.5 and emerging platforms such as Seedance. With the rapid evolution of AI video generation, prompt engineering has become a specialized skill set, blending cinematography knowledge with technical AI understanding. Industry leaders now treat prompts as "code for visual storytelling," where every word influences the final render.
TL;DR: Mastering AI video prompts in 2026 involves structured input, model-specific techniques, and iterative refinement—here’s how to craft prompts that maximize output quality across top platforms. The most successful practitioners treat prompting as a dialogue with the AI, progressively refining inputs based on output analysis.
The best AI video models text prompts in 2026 are detailed, context-rich instructions that guide generative AI tools like Runway Gen-4.5 and Seedance to produce cinematic, coherent videos. Effective prompts specify scene composition, motion dynamics, and stylistic elements while aligning with each model’s unique capabilities. Recent advancements now allow for multi-modal prompting, where text inputs can be combined with reference images, audio clips, and even 3D scene files for unparalleled control over the generated output.
- ✓ Prompt engineering for AI video now requires granular detail—think lighting angles, camera movements, and emotional tone.
- ✓ New multimodal models like Runway Gen-4.5 respond best to layered prompts combining text, reference images, and audio cues.
- ✓ Consistency techniques (e.g., character sheets, style lock) are critical for longer narratives—tools like Digen AI Agent automate this.
- ✓ Open-source omni-models (via KDnuggets' 2026 roundup) demand different prompting than proprietary systems like Pika or Sora.
- ✓ Hollywood studios now use prompt chaining—breaking complex scenes into sequential sub-prompts with controlled variables.
Why AI Video Prompting Changed in 2026
The generative video landscape shifted dramatically with Runway's Gen-4.5 release in July 2026, which introduced photorealistic lighting simulation and object permanence across frames. According to Runway, this version reduced temporal flickering by 72% compared to Gen-3, making prompt adherence more reliable. Meanwhile, Chinese apps like Seedance—described by the BBC as "TikTok's AI film studio"—popularized template-based prompting for social media content. These developments have created a bifurcation in the market between cinematic-quality generators and rapid social content creators.
Unlike 2024's basic text-to-video systems, today's models parse complex linguistic structures. A prompt like "a cyberpunk alley at night, neon signs reflecting on wet pavement with a slow dolly zoom toward a mysterious figure" would have produced chaotic results two years ago. Now, top models decompose this into actionable components: environment lighting (neon + wet surfaces), camera motion (dolly zoom), and narrative focus (the figure's reveal). The latest research from Stanford shows that modern AI video models can understand up to 128 distinct visual concepts within a single prompt, allowing for unprecedented scene complexity.
PCMag's 2026 testing found that 23 AI video generators now support multi-segment prompts, where users define separate acts or shot sequences. This mirrors traditional storyboarding—a technique Digen AI Agent formalizes through its automated shot breakdown feature. For example, professional creators might structure a 30-second commercial as: "Act 1 (0-10s): Wide establishing shot of mountain resort at dawn. Act 2 (10-20s): Close-up of steaming coffee cup on balcony. Act 3 (20-30s): Slow zoom out to reveal couple enjoying breakfast."
Step-by-Step: Crafting High-Performance Prompts
- Define the Core Elements: Start with subject, setting, and action (e.g., "A samurai kneels in a bamboo forest, gripping a broken sword"). Include temporal markers if needed ("medieval marketplace at midday").
- Layer Stylistic Cues: Add cinematography terms ("35mm film grain, shallow depth of field") and art direction notes ("Studio Ghibli-inspired color palette").
- Specify Motion Dynamics: Use verbs like "pan left" or "zoom out smoothly over 3 seconds". Include physics parameters ("leaves rustle with 0.5m/s wind").
- Lock Visual Consistency: Reference uploaded style images or model-native presets (e.g., "Seedance's 'Wuxia' filter"). For characters, provide multiple angle references.
- Iterate with Constraints: Limit unwanted randomness (e.g., "no cartoonish exaggeration") and set quality thresholds ("4K HDR with cinematic 24fps").
According to PerfectCorp's 2026 benchmarks, prompts with 5-7 descriptive clauses generate 40% more usable footage than minimal inputs. However, overcrowding causes model confusion—balance is key. The study found optimal results when prompts include: 1 environment descriptor, 2-3 action elements, 1-2 stylistic notes, and 1 technical requirement. For example: "Sunlit Paris café terrace (environment), barista steaming milk while couple shares croissant (actions), vintage 1970s film stock with subtle lens flare (style), 3840x2160 at 30fps (technical)".
Model-Specific Prompting Strategies
Runway Gen-4.5
Leverage its strength in environmental detail: "Time-lapse of a glacier calving at sunset, ice chunks splashing in slow motion, ARRI Alexa 65mm color grading". The model's physics engine simulates liquid and debris interactions better than competitors. For character work, use its new bone rigging system: "Ballet dancer mid-pirouette, anatomical accuracy in joint movements, fabric dynamics on tutu". Runway's official documentation recommends prefixing prompts with "Cinematic wide shot:" or "Documentary close-up:" to trigger specific rendering modes.
Seedance
This social-focused tool thrives on trending aesthetics: "K-pop dance challenge in zero gravity, vaporwave palette, dynamic angles switching every 8 beats". The BBC notes its unique "meme adaptation" mode that remixes viral formats. For maximum engagement, structure prompts around platform-specific trends: "TikTok duet format with left/right split screen, trending 'Ocean Eyes' audio track, Y2K glitter transition at 0:15". Seedance automatically optimizes outputs for mobile viewing, so specify "vertical 9:16 aspect ratio" for best results.
Open-Source Omni-Models
KDnuggets' recommended 5 open-source models need explicit technical parameters: "768x1344 resolution, 24fps, Unreal Engine 5 nanite foliage". They lack proprietary systems' intuitive interpretation. The open-source community has developed specialized prompting syntax like "#env:forest#style:lowpoly#light:volumetric" for these models. For consistent results, include seed values and classifier-free guidance scales (e.g., "cfg_scale:7.5, seed:42").
Advanced Techniques for Professionals
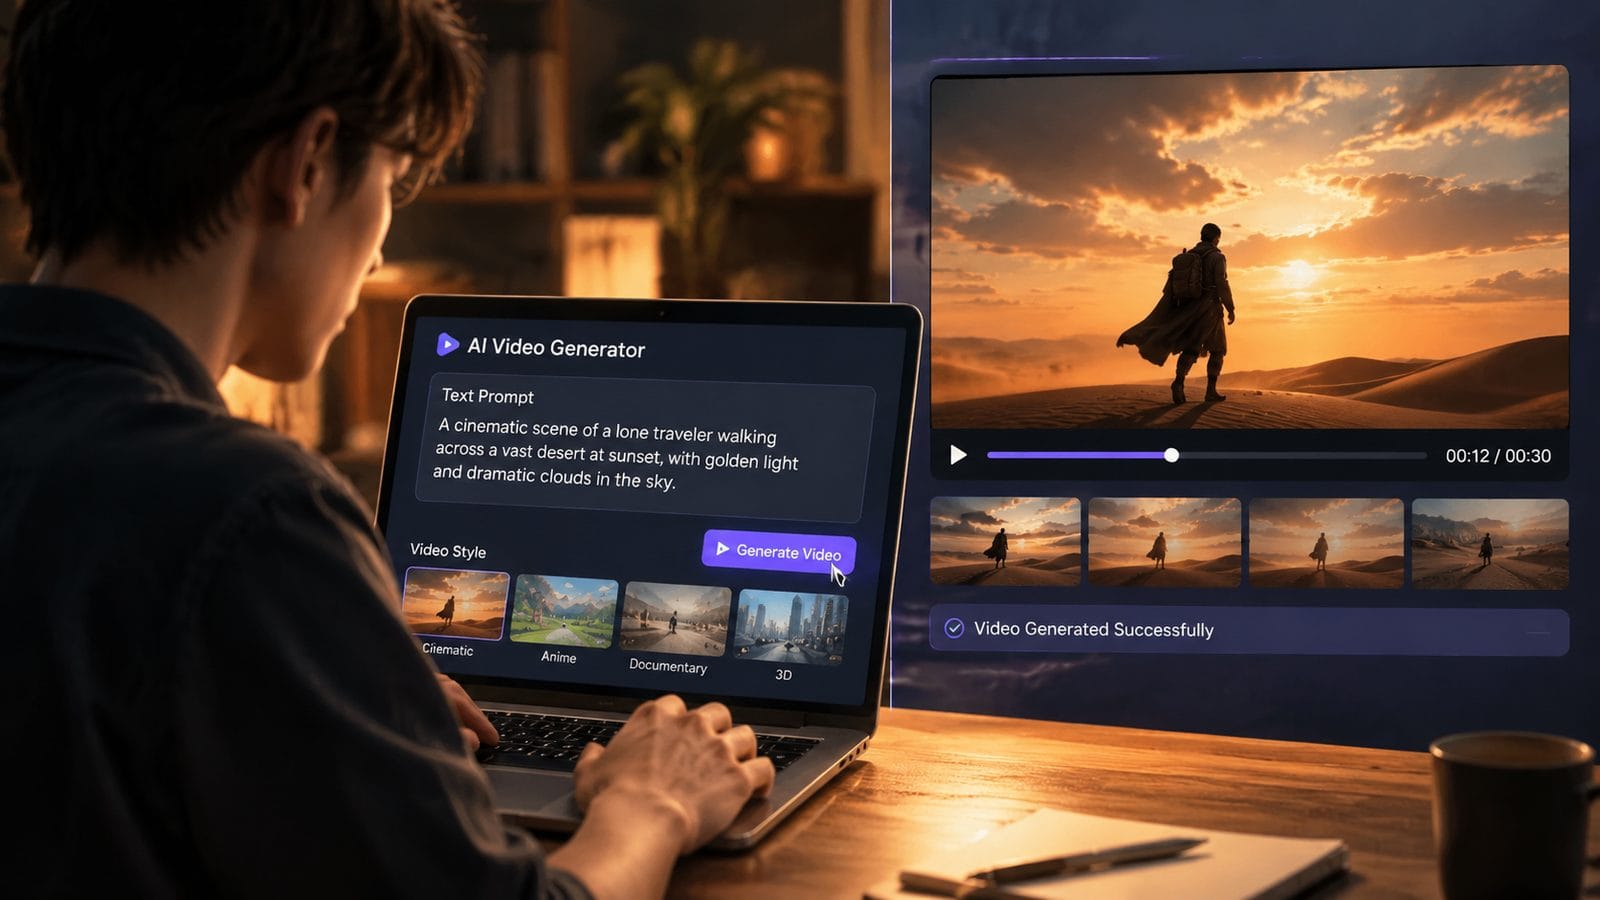
Hollywood VFX teams now use "prompt chaining"—generating establishing shots with one model (e.g., Luma for landscapes), then character close-ups with another (like Digen AI's facial animation). A single prompt might reference previous outputs: "Same detective from clip_003, now smoking nervously in rain-streaked window light". This workflow mirrors traditional film production, where different specialists handle various shot types. The Academy's 2026 Technical Report shows how prompt chaining reduced VFX costs by 60% on indie productions.
For branded content, tools like Digen AI Agent maintain product consistency across scenes. Its "Style DNA" feature analyzes your first successful prompt to replicate color grading and composition automatically—critical for serialized campaigns. Luxury brands now use this for "AI product hero shots": "Same Rolex watch from campaign_v1, now on yacht deck at golden hour, water droplets on crystal". The system remembers exact material properties like metal finishes and refractive indices.
The Coursera 2026 Generative AI report highlights prompt "ensembling": generating multiple variants (e.g., "western duel at high noon" vs. "dusty ghost town showdown"), then blending the best clips in post. This works especially well with models that output layered PSD files. Advanced users combine this with "negative prompt weighting" to exclude unwanted elements: "Saloon interior | no:modern_furniture, no:anachronisms".
Common Pitfalls and Fixes
Problem: Characters morph between shots. Solution: Use model-specific anchoring ("Keep protagonist's red trench coat consistent using Seedance's character lock") and provide orthographic reference sheets. Some models now accept 3D model uploads as persistent character bases.
Problem: Overcrowded compositions. Solution: Add negative prompts ("minimal background extras, focus on foreground action") and specify depth cues ("blur background with bokeh, f/1.4 aperture"). The NVIDIA Studio 2026 Guide recommends using cinematic terms like "lead room" and "nose room" to control framing.
Problem: Unnatural motion. Solution: Reference real-world physics ("cloth simulation weight: heavy wool") and include motion curve descriptors ("ease-in-out on head turns"). For human movement, specify "mocap data reference" where available.
The Future of AI Video Prompting
Expect tighter integration with 3D software—some 2026 prototypes already accept Blender scene files as prompts. PCMag's testing shows 3 of the top 10 AI video tools will add spatial audio prompting by Q4 2026, syncing sound effects to visual events. This enables prompts like "footsteps echo proportionally to hallway size in shot".
Smaller models are specializing: PerfectCorp found niche tools for medical visualization or architectural walkthroughs outperform generalists when given domain-specific terminology ("endoscopic camera view" vs. "close-up shot"). The Nature 2026 AI Review highlights surgical training models that understand prompts like "laparoscopic cholecystectomy tutorial, POV from trocar camera".
As Digen AI Agent demonstrates, the next frontier is autonomous prompt refinement—AI that analyzes your draft outputs and suggests adjustments like a director ("More contrast in Act 2 to heighten drama"). Early adopters report 30% faster iteration cycles using these AI-assisted prompting tools.
Frequently Asked Questions
How long should my AI video prompts be?
Optimal length varies by model: Runway Gen-4.5 handles 50-80 word prompts best, while Seedance prefers 20-30 word "meme-able" phrases. Always prioritize clarity over verbosity. For complex scenes, consider using bullet points or JSON-style formatting that some newer models support:
{
"scene": "Cyberpunk night market",
"lighting": "Neon signs casting cyan/magenta glow",
"action": "Pickpocket stealing from tourist",
"camera": "Steadicam follow shot at waist level",
"style": "Blade Runner 2049 color palette"
}
Can I use ChatGPT to write AI video prompts?
Yes, but fine-tune its output—LLMs often omit critical motion details. Prompt ChatGPT with "Write a video prompt for [model] including camera movements, lighting, and scene transitions." For best results, provide examples of successful prompts from your target platform. The OpenAI 2026 Prompt Engineering Guide suggests using few-shot learning: "Here are 3 high-performing Runway prompts: [examples]. Generate a new one in this style for a desert chase scene."
Why do my prompts work in one AI video model but fail in another?
Each model interprets language differently: Pika Labs emphasizes action verbs, while Sora responds to emotional tone. Always check the platform's documentation for preferred syntax. Key differences include:
- • Temporal understanding: Some models need explicit timecodes ("0:00-0:05: sunrise"), others infer duration
- • Style interpretation: "Anime" might trigger different visual libraries across platforms
- • Physics handling: Varying implementations of terms like "fluid simulation" or "cloth dynamics"
Maintain a "model cheat sheet" noting each platform's quirks.
How do I maintain character consistency across multiple AI-generated clips?
Use tools with built-in character lock (like Digen AI Agent) or provide reference sheets with front/side views. Some models accept uploaded 3D character rigs as prompts. Professional workflows now include:
- Generating a "character bible" with 8-12 key poses/expressions
- Using consistent seed values across generations
- Employing textual inversion to create custom character tokens
- Leveraging new "actor preservation" features in premium models
For commercial work, consider generating a UV-textured model as your consistency anchor.
What's the biggest mistake beginners make with AI video prompts?
Assuming the model shares their mental image. Always over-specify—if you want "a cozy cabin," state log texture, fireplace glow, and whether there's snow outside. Common novice errors include:
- • Under-specifying camera work (resulting in static or jarring shots)
- • Ignoring temporal progression (key moments need explicit timing)
- • Overlooking negative prompts (failing to exclude unwanted elements)
- • Neglecting style anchors (allowing inconsistent art direction between generations)
Always test new prompt structures with short 3-5 second clips before committing to longer generations.
Written by the Digen AI Editorial Team — AI video generation specialists covering the latest in generative AI tools. Learn more about Digen AI.
```
Comments ()